
AI ROI (return on investment in artificial intelligence) measures the financial value an AI initiative produces compared with what it costs to build, run, and maintain. The formula is simple, but the inputs aren’t.
Token-based pricing means your AI bill moves with usage, not with a contract, and most teams can’t see which workloads are driving it until they get the invoice.
That gap is getting expensive. Gartner recently forecasted worldwide AI spending will reach $2.59 trillion in 2026, up 47% from 2025.
At the company level, that pressure shows up fast: Uber reportedly used up its entire 2026 AI coding-tools budget in about four months, and its COO has since said the spend is getting harder to justify.
In this guide, you’ll get a practical framework for measuring AI ROI:
- What to count
- Which metrics matter
- How to find spend that isn’t paying off
- How to set guardrails before you scale further
What Is AI ROI? Defining Return on Investment in Artificial Intelligence
AI ROI compares the value an AI tool or workflow creates against its total cost over a defined period.
The standard formula looks like this:
AI ROI = (Value generated − Total AI cost) ÷ Total AI cost × 100
Value generated includes hard returns and soft returns:
Hard returns: labor hours saved, contractor or vendor costs avoided, revenue lift, and reduced errors and rework
Soft returns: faster cycle times, higher output per employee, better decision quality
Total AI cost is more than the API bill. It includes tokens, seat licenses, infrastructure, engineering and integration time, monitoring tools, and governance overhead.
A Worked Example
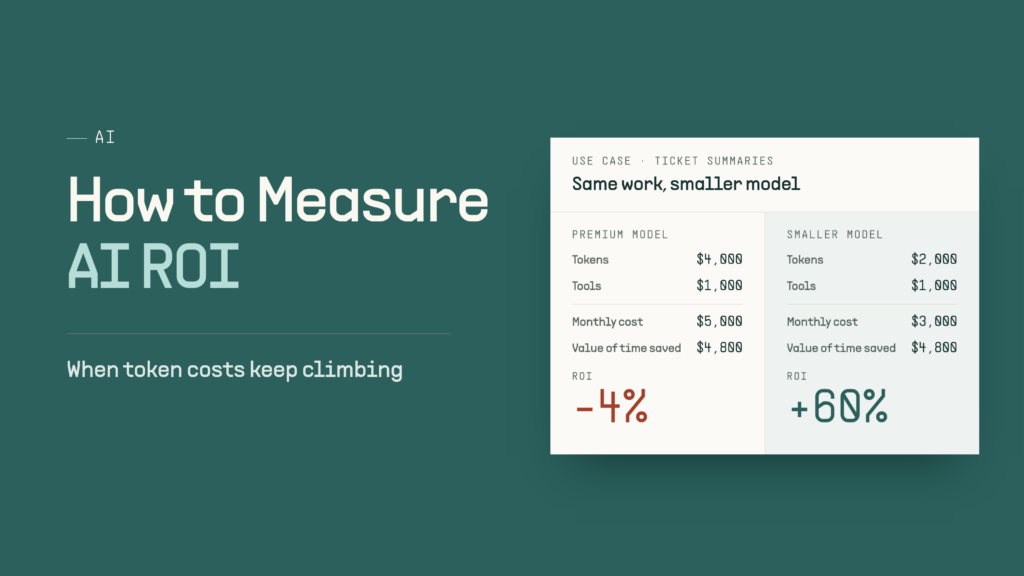
Say your support team uses an LLM to summarize tickets. Monthly cost: $4,000 in tokens plus $1,000 in tooling, or $5,000 total. The workflow saves 120 agent hours at a loaded rate of $40 per hour, worth $4,800.
ROI = ($4,800 – $5,000) ÷ $5,000 = –4%. The tool works. It just costs more than it returns. Route the same job to a smaller model at half the token cost, and ROI swings to roughly +60%.
That’s why you want to measure AI ROI per use case and not per AI budget.
How Much Does AI Cost?
AI costs come from several billing models at once, and finance usually sees only part of them. Per-token prices for a given capability level keep falling, but total bills keep rising because consumption grows faster, especially as agentic workflows call the model again at every step.
| Cost component | How it’s billed | What drives it | Finance visibility |
|---|---|---|---|
| API tokens (OpenAI, Anthropic, etc.) | Per million input and output tokens | Model choice, prompt size, output length, caching | Low |
| Agentic workloads | Per token, across many steps | Loops, retries, tool calls, long context | Very low |
| Seat licenses | Per user per month | Headcount, plan tier | High |
| Infrastructure and hosting | Compute hours, GPU capacity | Self-hosted or fine-tuned models | Medium |
| Engineering and integration | Salaries, contractors | Build, maintenance, prompt tuning | Medium |
For a deeper breakdown of each line item, see our guide to tracking, auditing, and reducing LLM spending.
Why Token Pricing Makes AI ROI Hard to Measure
With most purchases, you’ll know the price before you decide to buy. With token-based AI, you only learn what the task costs after the model finishes it.
Several factors make this worse:
- No purchase order. Usage scales with every new prompt, user, or automation. Nobody approves the incremental spend.
- Shared or untagged API keys. When five teams use one key, nobody owns the cost. Tools bought on personal or departmental cards add shadow AI spend that never reaches a central budget.
- Prompts that grow over time. System prompts, chat history, and retrieved context pile up, so the same task costs more each month. This is prompt bloat, and it rarely shows up on a dashboard.
- Model upgrades. Teams default to the newest, most capable model, even for jobs a cheaper model handles fine.
- Lagging invoices. Provider bills arrive monthly. By the time you see a spike, the money is gone.
Which Metrics Should Companies Use to Measure AI ROI?
The right AI ROI metrics connect token spend to business outcomes. Use a mix of leading indicators (which predict whether ROI will materialize) and lagging indicators (which confirm it did).
| Metric | How to calculate it | What it tells you | Type |
|---|---|---|---|
| Cost per outcome | Total AI cost ÷ outcomes delivered (tickets resolved, drafts produced, leads qualified) | Whether the use case is cheaper than the old way | Lagging |
| Value of time saved | Hours saved × loaded hourly rate | Dollar value of productivity gains | Lagging |
| Adoption rate | Active users ÷ licensed users | Whether people actually use what you’re paying for | Leading |
| Cost per active user | AI cost ÷ users active in the period | True per-head cost, net of unused seats | Leading |
| Spend by workload or key | Token cost grouped by API key, team, or project | Who owns the cost and where it’s concentrated | Leading |
| Budget variance | (Actual − forecast) ÷ forecast | How predictable your AI spend is | Leading |
| Premium model share | Spend on top-tier models ÷ total token spend | Whether you’re overpaying for capability | Leading |
| Cache hit rate | Cached input tokens ÷ total input tokens | How much repeat context you pay full price for | Leading |
A 5-Step Framework for Measuring AI ROI
1. Inventory Every AI Cost
Pull every AI-related charge into one view: API invoices, seat subscriptions, AI features bundled into existing software, and tools expensed on employee cards. Most teams find more vendors than they expected. The same discipline you’d apply to SaaS spend management applies here.
2. Attribute Spend to Owners and Workloads
Give each workload its own API key, tag keys by team and project, and pay each AI vendor from a dedicated virtual card. If you can’t attribute the spend, you won’t be able to evaluate it.
3. Set a Baseline Before You Deploy
Define the outcome and measure the current cost of producing it: hours per task, cost per ticket, and turnaround time. Without a pre-AI baseline, you have nothing to compare against.
4. Calculate Unit Economics
Translate token spend into a cost per outcome: (tokens used × cost per token + fixed costs) ÷ outcomes delivered. The FinOps Foundation’s work on token economics recommends unit metrics like cost per query, cost per user, and cost per workflow to make token spend legible to business stakeholders.
5. Sort Every Use Case Into Keep, Fix, or Cut
| Decision | Criteria | Next step |
|---|---|---|
| Keep | Cost per outcome is below baseline, adoption is healthy | Scale, with budget alerts in place |
| Fix | Value is real, but cost per outcome is too high | Route to a smaller model, enable caching, trim prompts |
| Cut | No measurable outcome after the agreed review window | Revoke keys, cancel seats, reallocate budget |
How to Find AI Spend That Isn’t Paying Off
Waste in AI spend usually follows recognizable patterns. Look for signals in your usage data:
| Signal | What it usually means | Fix |
|---|---|---|
| Premium model running summarization or classification | Oversized model for the job | Route simple tasks to a smaller model |
| Low cache hit rate on repeated prompts | Paying full price for the same context | Enable or fix prompt caching |
| Cost per request climbing month over month | Context inflation or prompt bloat | Trim history and system prompts |
| Untagged or stale API keys still spending | No owner, possible leaked credentials | Rotate, tag, or revoke |
| Off-hours or weekend spikes | Runaway scripts, agent loops, retries | Rate limits and anomaly alerts |
| Seats with few or no logins | Unused licenses | Reclaim and right-size plans |
How to Set AI Cost Guardrails
Guardrails let teams keep using AI without blank-check spending. The goal is predictability, not prohibition.
- Budgets by team and workload, with alerts at 50%, 80%, and 100% of the monthly target
- Spend caps per API key or per user, so one runaway script can’t consume a quarter’s budget
- Dedicated virtual cards for each AI vendor, with limits and merchant restrictions so your AI cards pay your AI vendors and nothing else
- A model routing policy that defines which tasks require premium models and which default to smaller ones
- An approval workflow for new AI tools, so new vendors enter the inventory before they enter the budget
- A monthly review where finance and engineering walk through cost per outcome and the keep/fix/cut list together
Why an AI Spend Audit Comes Before Scaling AI
Scaling AI on top of unmeasured spend multiplies whatever waste already exists. If a third of today’s token spend goes to oversized models and cache misses, doubling usage doubles that waste too.
Most finance teams can’t measure this yet: only 35% of respondents in Protiviti’s 2026 Global Finance Trends Survey said they were highly or moderately effective at measuring AI ROI.
An AI spend audit gives you the baseline the rest of the framework depends on. A thorough audit should:
- Break down spend by provider, model, API key, and team
- Reconcile what the provider billed against expected pricing
- Flag waste patterns, from model mismatches to stale keys
- Rank findings by monthly dollar impact
- Produce an action plan with an owner for each fix
The Dash.fi AI Spend Audit does this for Anthropic and OpenAI. You connect read-only admin keys, with no code changes, and the agent breaks down spend by model and API key, flags issues like oversized models, prompt cache misses, and untagged keys, and checks provider charges against the rate card.
Findings feed a prioritized Action Plan ranked by monthly impact, so your engineers know what to fix first. AI spend on the Dash.fi card also earns up to 3% back, depending on your payment terms.
Frequently Asked Questions
What is a good ROI for AI?
There’s no universal benchmark. A use case delivers good AI ROI when its cost per outcome is meaningfully lower than the pre-AI baseline and stays there as usage grows. Measure ROI per use case rather than across your whole AI budget, since strong and weak projects average each other out.
How long does it take to see ROI from AI?
Efficiency use cases like summarization, drafting, and data extraction often show measurable results within one or two quarters. Experimental or customer-facing projects take longer. Set the review window before launch so you know when to make a keep, fix, or cut decision.
Why are AI costs rising if token prices are falling?
Consumption is growing faster than prices are dropping. Teams use AI for more tasks, prompts get longer, newer models cost more per token, and agentic workflows make many model calls for a single task.
What’s the difference between AI cost and AI ROI?
AI cost is what you spend. AI ROI is what that spend returns relative to its cost. A rising AI bill isn’t a problem on its own if cost per outcome is falling. It becomes one when spend grows and outcomes don’t.
Should you cut AI spend to improve ROI?
Not across the board. Blanket cuts hit productive use cases along with wasteful ones. Audit first, then cut or fix the specific workloads that aren’t returning value and scale the ones that are.